Solutions

Multimodal Vision + EEG Data Acquisition ODM — hardware-level synchronization between vision and EEG channels, one-stop delivery from hardware to SDK

🧠 EEG Multimodal · ODM Customization

Multi-Camera Vision + 1024-Channel EEG Multimodal Data Acquisition ODM Service

For brain-computer interface (BCI) research and embodied-AI perception fusion, we offer a custom multimodal data acquisition terminal featuring 6-camera forehead vision + 1024-channel EEG: hardware-level synchronized sampling across vision and EEG channels, delivered end-to-end from hardware design and system firmware to SDK data review.

  • 6-camera forehead vision: 2K RGB ×2 + 720p grayscale ×4, global shutter, multi-angle head-mounted coverage of the operating area
  • 1024-channel EEG: high-density EEG acquisition, frame-synchronized timestamps with the vision stream
  • EEG ↔ vision hardware sync: hardware-level synchronized sampling of EEG and vision channels
  • Sync error <50μs: multi-channel time-alignment accuracy better than 50 microseconds
  • SDK multi-channel data review: synchronized review of vision streams and EEG waveforms, with offline playback and live preview
  • ODM delivery: hardware production files / firmware / enclosure / SDK / calibration SOP, with long-term customization supported
🧬 Multimodal Hard-Sync Acquisition Architecture · Sync Error <50μs
🎥
Vision Subsystem · 6 Forehead Cameras
2K RGB ×2 + 720p grayscale ×4 · global shutter
🧠
EEG Subsystem · 1024 Channels
High-density EEG · multi-channel synchronized sampling
⏱ Hardware-Level Sync · EEG ↔ Vision <50μs
EGO Multimodal Sync Hub
Unified trigger & timestamping · vision + EEG + IMU time alignment
▼
📊 SDK · Multi-Channel Data Review
Synchronized preview / playback of vision streams + EEG waveforms · multi-channel timing review
🎥
6 Cam
Forehead Vision Array
2K RGB ×2 + 720p grayscale ×4, global shutter head-mounted view
🧠
1024
EEG Channels
High-density EEG acquisition, frame-synchronized with vision
⏱
<50μs
Hardware Sync Error
Hardware-level synchronized sampling of EEG and vision channels
📊
SDK
Multi-Channel Data Review
Synchronized preview of vision + EEG waveforms, offline playback

🧬 Ego-NeuroLoop: From Multimodal Acquisition to Trainable Embodied-AI Data

From low-cost multimodal acquisition (NeuroMatrix), to closed-loop paired mapping (Ego-NeuroLoop), to neural-signal VLM alignment (NeuroBooster), ultimately producing structured closed-loop representations for Embodied AI training — a complete "perception → intent → action → feedback" closed-loop data pipeline.
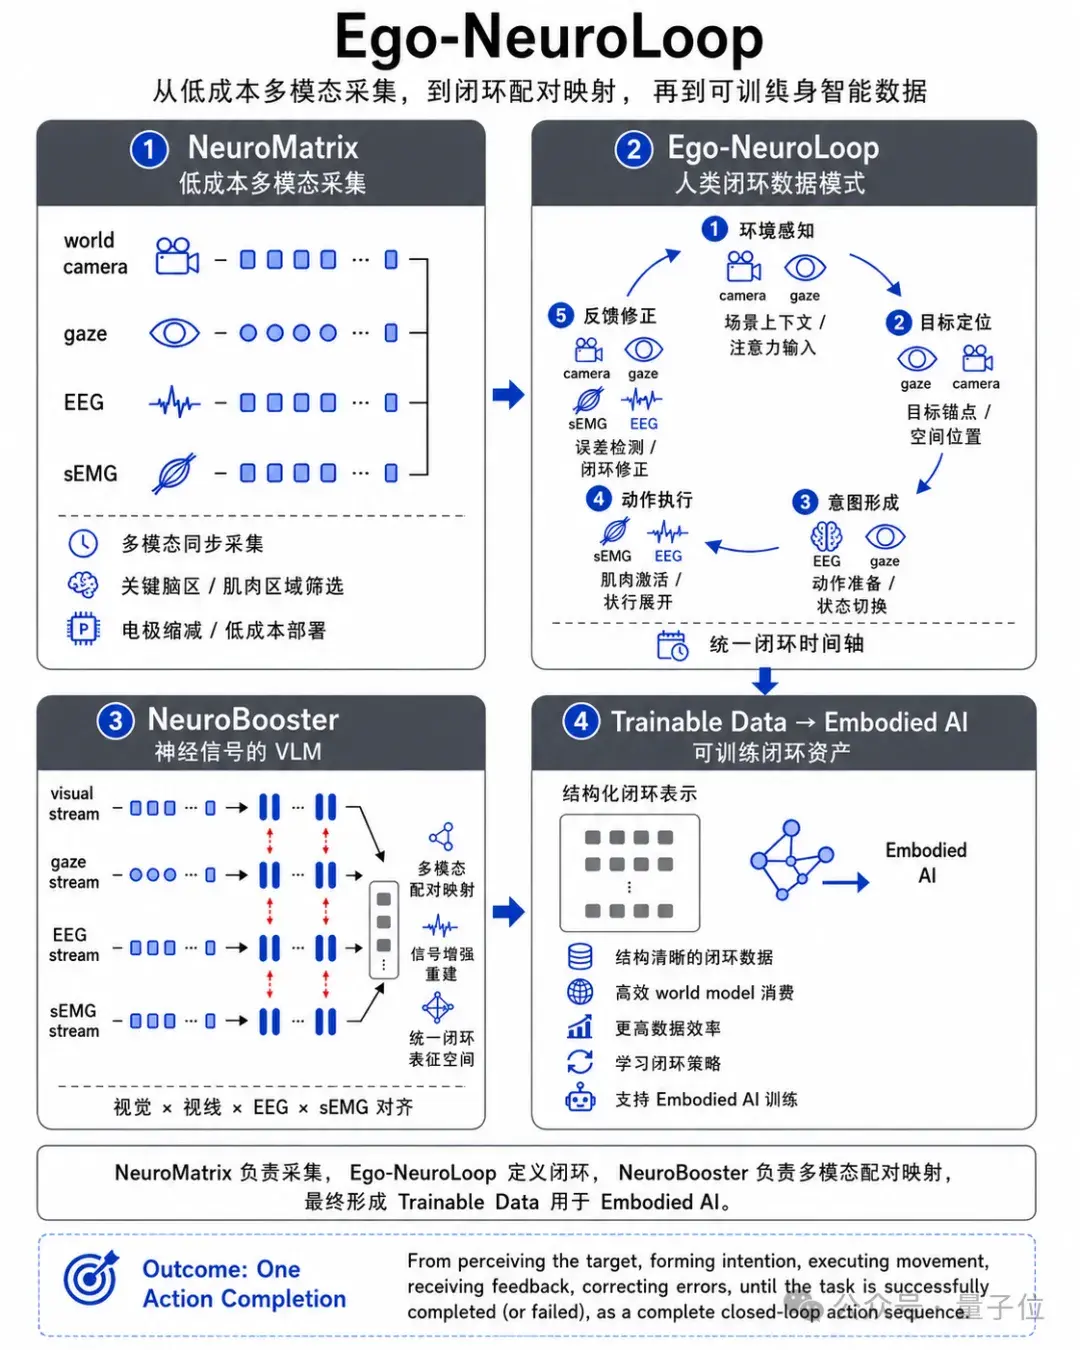
Ego-NeuroLoop multimodal neuro-electrical data acquisition closed-loop architecture
①
NeuroMatrix
Low-cost multimodal acquisition
world camera · gaze · EEG · sEMG
②
Ego-NeuroLoop
Human closed-loop data pattern
environment perception → intent formation → action execution → feedback correction
③
NeuroBooster
Neural-signal VLM
vision × gaze × EEG × sEMG multimodal alignment
④
Trainable Data
Trainable closed-loop assets
structured representations → Embodied AI
▶ EGO × sEMG armband · multimodal synchronized capture results (video narration in Chinese)
🧤 Neural Bioelectric Multimodal · Ego + EMG Wristband

sEMG × Hand MANO 6DoF Ground Truth: Infrastructure for the "Data Race" in Neural Decoding

The competition in neural decoding has shifted from algorithms to data. Meta Reality Labs' surface-EMG research published in Nature in July 2025 (the sEMG-RD wristband: 300 subjects, 100+ hours of data, a generic decoder requiring no per-user calibration) has confirmed that EMG decoding performance keeps improving along a "scaling law" as data and model size grow — the core competitive edge in neural bioelectrics will belong to whoever can build large-scale paired datasets at lower cost and higher precision.

⚠️ Industry Status · Data-Paradigm Bottleneck
Most EMG training data carries only discrete gesture classification labels (fist / pinch / extend) — telling the model "what gesture was made" while losing the continuous information of "how the hand actually moved", severely capping neural-decoding performance.
→
✅ Our Proposal · Joint 6DoF Ground-Truth Acquisition
Synchronized acquisition with an sEMG wristband + the EGO multi-camera terminal + a wrist EMF pose ground-truth glove, outputting per-frame 21 keypoints × 6DoF continuous joint states (regressing the MANO hand mesh) with hardware-level sync of <50μs, aligning "electrical signals — motion states" strictly frame by frame.
  • Data modality: three-source synchronized acquisition — sEMG wristband signals + EGO multi-camera terminal (egocentric vision) + wrist EMF pose ground-truth glove (21 × 6DoF hand ground truth)
  • Ground-truth system: sub-millimeter hand joint pose ground truth, regressing the MANO hand mesh model, forming a 21-keypoint × 6DoF continuous joint-state supervision signal
  • Hardware-level sync: vision frames and EMG samples timestamped in hardware with sync error <50μs, strictly aligned frame by frame
  • Companion capabilities: SDK multi-channel review (video stream + EMG waveforms + hand-mesh overlay with synchronized playback) + ODM synchronization support
🧤 EMG + Hand Ground-Truth Sync Acquisition Architecture · Sync Error <50μs
🎥
EGO Multi-Camera Terminal
Egocentric vision · full view of hand manipulation
⚡
EMG Wristband · sEMG
Gesture-intent bioelectric signals · high-bandwidth neural decoding
🧤
EMF Pose Tactile Glove
Hand MANO mesh · 21 keypoints × 6DoF pose ground truth
⏱ Hardware-Level Sync · Vision Frames + EMG Sampling + Glove Ground Truth <50μs
EGO Multimodal Sync Hub
Unified trigger & timestamping · vision + sEMG + EMF glove + IMU all-modal alignment
▼
📊 Paired Dataset → Neural-Decoding Training
Continuous joint-state supervision · regression/generative decoding · reproducible scaling law
▶ EMF Pose Tactile Glove · hand MANO 6DoF ground-truth demo (video narration in Chinese)
🖐️
21×6DoF
Hand Ground-Truth Supervision
MANO mesh regression · continuous per-frame joint states
🧤
sEMG
EMG Wristband
Research/consumer wristband compatible with the Meta sEMG-RD approach
⏱
<50μs
Sync Error
Electrical signals and motion states aligned strictly frame by frame
🧬
Scaling
Law Performance Gains
More data ↑ → generalized decoding performance ↑
🎯 Three Values of 6DoF Ground-Truth Supervision for EMG Neural-Decoding Training
From "classification" to "regression/generation", breaking through the label-information bottleneck
🔁
From Classification to Regression/Generative Decoding
Discrete gesture labels are one-shot classification signals from which models only learn "class boundaries"; 6DoF joint ground truth is a continuous, time-varying supervision signal covering full hand kinematics — leaping from "recognizing which gesture was made" to "continuously predicting per-frame joint states", supporting precision-critical applications such as prosthetics/dexterous-hand fine control, continuous writing and sign-language motion.
📈
Ground-Truth Pretraining · Faster Scaling-Law Reproduction
Every EMG segment carries complete supervision information (rather than a single label), sharply raising information density for the same data volume; ground truth is naturally suited to self-supervised/regression pretraining, allowing earlier approach to the generalization curve Meta has demonstrated even with limited data — or equal performance with less data.
🌐
An "Interpretable" Bridge for Cross-Population Generalization
Meta has shown personalized fine-tuning further improves recognition by 16%. 6DoF ground truth provides a quantitative reference for inter-individual kinematic differences — joint-motion differences can be precisely described in ground-truth space, turning "personalized adaptation" from black-box tuning into interpretable kinematic modeling for a stable cross-user experience at scale.
🤝 Partnership Model · Building a Domestic Data Pathway with EMG Hardware Teams
EMG decoding hardware/algorithm expertise × EGO ground-truth acquisition and synchronization = a domestic data pathway on par with Meta
🧪
Joint Acquisition Pilot
A small pilot run (10–20 units) to jointly acquire "EMG + hand ground truth" paired data and align data formats, quickly validating pipeline feasibility.
🗂️
Joint Dataset Development
Co-build the first EMG–hand 6DoF ground-truth dataset for Chinese/domestic populations, claiming the academic and industrial standard-setting high ground.
🔌
SDK Integration
Our SDK reserves an EMG channel interface, supporting partners' data formats and synchronized playback (video stream + EMG waveforms + hand-mesh overlay).

💡 What This Unlocks for Neural-Bioelectric Teams

Meta has proven generic sEMG decoding feasible — the remaining battleground is "data". We make it affordable for every team to build its own vision + neural-bioelectric paired dataset

💰
Lower Data Costs
The EGO ODM package starts at RMB 1,800 per complete unit, driving "vision + EMG" paired data acquisition costs to an industry low — startups no longer priced out of building datasets.
⏱
Annotation-Free Ground Truth
Sub-millimeter hand joint pose ground truth is output in sync with EMG and auto-aligned with gesture labels — no manual per-gesture annotation; go straight to model training.
🧬
Replicate the Meta Paradigm
Performance follows a "scaling law" as data and model size grow. EGO provides the data-acquisition infrastructure so domestic teams can build generic sEMG decoders along the same path, free from overseas ecosystem constraints.
🔧
One-Stop ODM Delivery
From research prototype to productization: hardware production files, synchronization design, firmware, enclosure, SDK and calibration SOP delivered end-to-end, with the <50μs sync error of a proven design reused directly.
🎯
Rapid Scenario Deployment
For rehabilitation medicine (hand motor impairment), human-computer interaction, brain-computer interface (BCI) research, AR/VR gesture control and more — validate while collecting data, shortening the path from research to deployment.
📊
SDK Ecosystem Compatibility
The multi-channel review SDK works with mainstream EMG wristbands and research-grade sEMG devices, with synchronized preview/playback of vision streams and EMG waveforms and unified cross-device data formats.

📄 Reference: Meta Surface-EMG Research (Nature, 2025)

  • Paper: A generic non-invasive neuromotor interface for human-computer interaction — Meta Reality Labs, Nature (2025)
  • Technology: the sEMG-RD wristband decodes gesture intent from wrist surface EMG signals — non-invasive, no per-user calibration required
  • Data: 300 subjects, 100+ hours of surface-EMG recordings; a public dataset released to enable larger-scale research
  • Performance: cross-population out-of-the-box generalization + 16% recognition gain from personalized fine-tuning; 20.9 words per minute for in-air handwriting
  • Implication: decoding performance follows a "scaling law" — data and model size are the core variables, which is exactly where the EGO multimodal acquisition solution fits in
🦾 Neuro-bioelectric Prosthetics · 6DoF Ground-Truth Supervision

Ego + EMG Wristband: 6DoF Ground-Truth Supervision for Neuro-bioelectric Prosthetics

For neuro-bioelectric prosthetic hand and leg startups: we provide a joint "vision + EMG + hand joint 6DoF ground truth" acquisition solution. Using continuous kinematic ground truth instead of discrete gesture labels as supervision, we advance EMG decoding from "recognizing gesture classes" to "continuously predicting joint states", delivering next-generation training-data infrastructure for fine prosthetic control and gait control.

  • Joint acquisition: the EGO multi-camera terminal (egocentric vision + sub-millimeter hand joint ground truth) synchronized with your neuro-bioelectric prosthetic device (sEMG / electrode signals)
  • MANO mesh ground truth: per-frame 21-keypoint × 6DoF continuous joint-state supervision signal, regressing the MANO hand mesh
  • Hardware-level sync: vision frames and EMG samples timestamped in sync, error <50μs
  • SDK review: synchronized playback of video stream + EMG waveforms + hand-mesh overlay
  • ODM support: end-to-end delivery of synchronization design / hardware / firmware / calibration SOP
🦾 Neuro-bioelectric Prosthetics Training-Data Loop · Sync Error <50μs
🎥
EGO Multi-Camera Vision
Egocentric RGB / grayscale / IMU · full view of hand motion
🦾
Neural Bioelectric Signals
sEMG / electrode signals · residual-limb EMG acquisition
⏱ Hardware-Level Sync · EMG ↔ 6DoF Joint Ground Truth <50μs
🎯 6DoF Ground-Truth Generation (MANO Mesh · 21 Keypoints)
Continuous joint-state supervision signal · no manual labels
▼
🦾 Neural-Decoding Model → Fine Prosthetic Control
Regression decoding · multi-DoF prosthetic-hand grasping / prosthetic-leg gait-phase control
🦾
6DoF
Joint Ground-Truth Supervision
21 keypoints × 6DoF continuous kinematic supervision signal
🎯
Regression
Neural-Decoding Paradigm
From gesture classification to continuous joint-state prediction
⏱
<50μs
Sync Error
EMG signals and ground truth aligned strictly frame by frame
🤝
1:1
Personalized Amputee Fitting
Interpretable modeling of individual kinematic differences in ground-truth space

💡 Three Values of 6DoF Ground-Truth Data for Prosthetic Neural-Decoding Training

Partnering with neuro-bioelectric prosthetic hand and leg startups to co-build "EMG signal — continuous kinematic ground truth" datasets, breaking the information bottleneck of classification labels

🦾
Fine Control: Regression / Generative Decoding
Discrete gesture labels are one-shot classification signals from which models only learn "class boundaries"; 6DoF joint ground truth is a continuous, time-varying supervision signal covering full hand kinematics — models leap from "recognizing which gesture the user made" to "continuously predicting per-frame joint states", supporting high-precision applications such as multi-DoF prosthetic grasping, continuous writing and dexterous-hand operation that classification paradigms cannot reach.
🧬
Ground-Truth-Driven Pretraining: Faster "Scaling Law" Reproduction
Meta's paper revealed "more data ↑ → generalization ↑". 6DoF ground truth lets every EMG segment carry complete supervision information (rather than a single label), sharply raising information density; ground truth is naturally suited to self-supervised / regression pretraining, so prosthetics startups can approach Meta's demonstrated generalization curve earlier even with limited data — or achieve equal performance with less data.
🤝
An "Interpretable" Bridge for Cross-Population Generalization and Personalized Fine-Tuning
Meta has shown personalized fine-tuning further improves recognition by 16%. 6DoF ground truth provides a quantitative reference for inter-individual kinematic differences — residual-limb differences and compensatory motion patterns across amputees can be precisely described in ground-truth space, turning "personalized fitting" from black-box tuning into interpretable kinematic modeling and ensuring a stable cross-user experience as prosthetic products scale.

🤝 Partnership Model for Neuro-bioelectric Prosthetics Startups

  • Joint data-acquisition pilot: a small prototype run (e.g., 10–20 units) to complete "EMG + 6DoF ground truth" paired data acquisition and format alignment
  • Joint dataset development: co-build the first domestic "amputee / varied-mobility population" EMG–hand / gait 6DoF ground-truth dataset
  • Ground-truth acquisition ODM: EGO terminal + synchronization design + SDK delivered end-to-end, so prosthetics startups can focus on decoding algorithms and productization
  • Extended scenarios: prosthetic hands (multi-finger grasping / pinch / fine manipulation), prosthetic legs (gait phase / stairs / balance), rehabilitation training assessment, dexterous-hand teleoperation

Need a Custom EEG Multimodal Acquisition Solution?

Our technical team will get back to you within 24 hours

Consult Now →